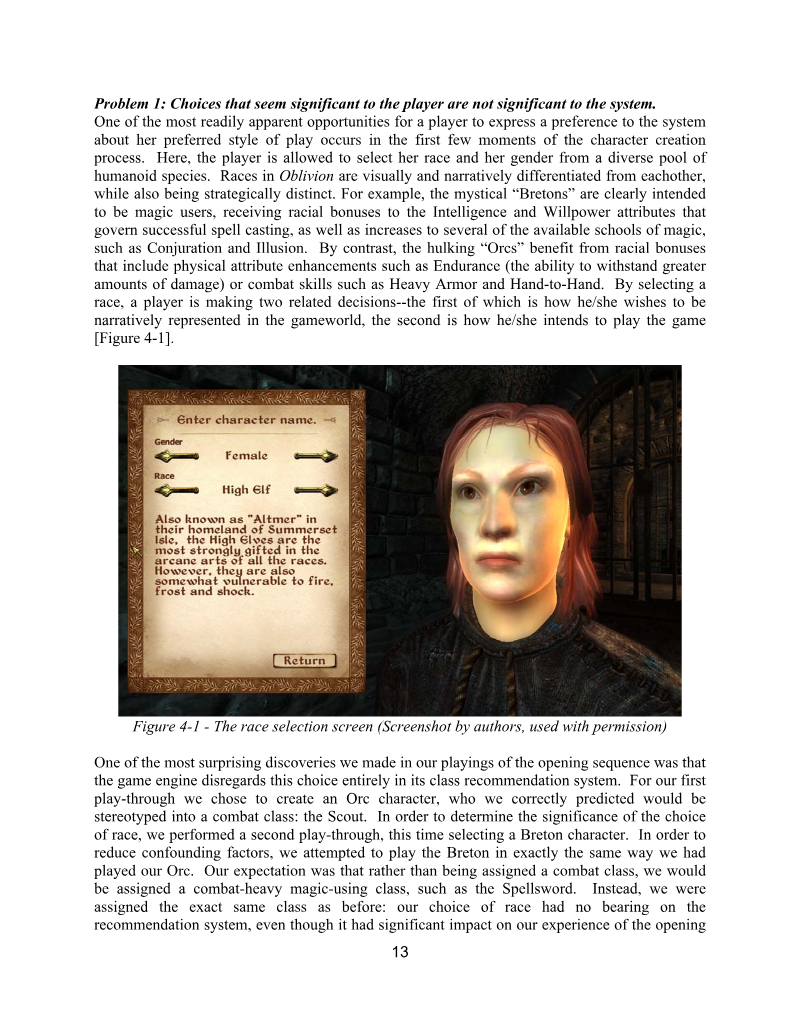
This research explores the utility of video games as a rich, professionally annotated corpus for natural language processing (NLP) tasks, specifically focusing on multilabel sentiment analysis. By leveraging the dialog from the open-world role-playing game Fallout New Vegas, the study extracts a multilingual dataset featuring over 53,000 lines of dialogue pre-annotated with eight distinct sentiment labels: anger, disgust, fear, happy, neutral, pained, sad, and surprised. The dataset covers five languages—English, Spanish, German, French, and Italian—providing a unique, high-value resource for cross-lingual sentiment modeling.
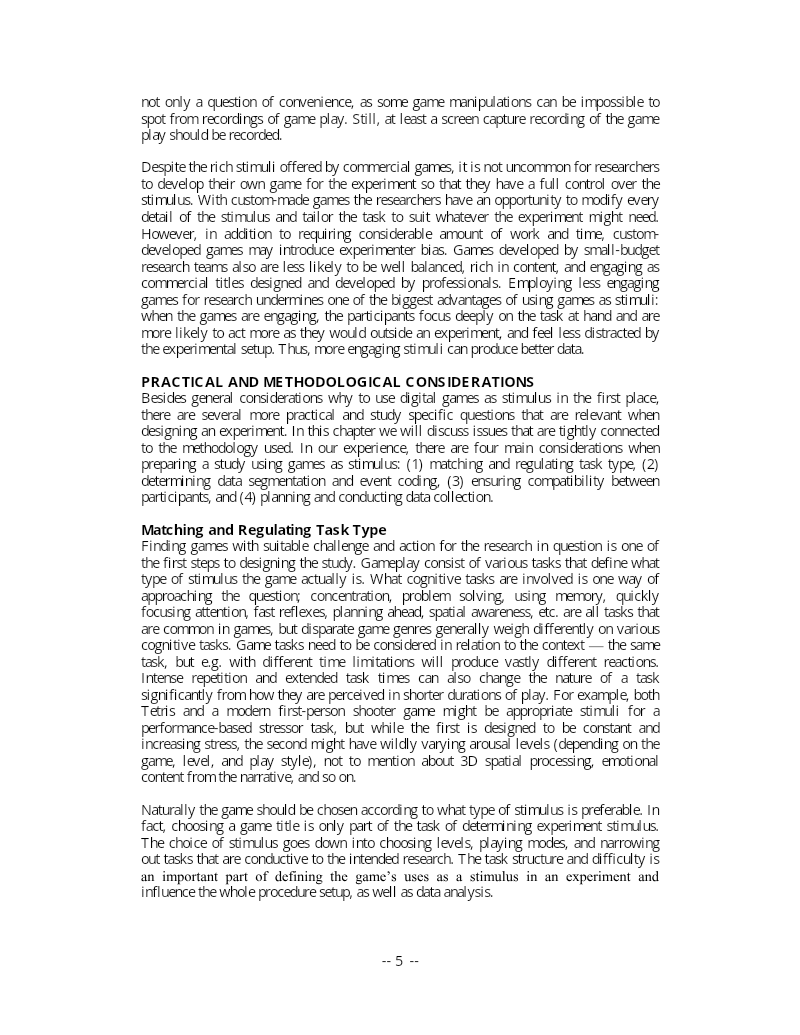
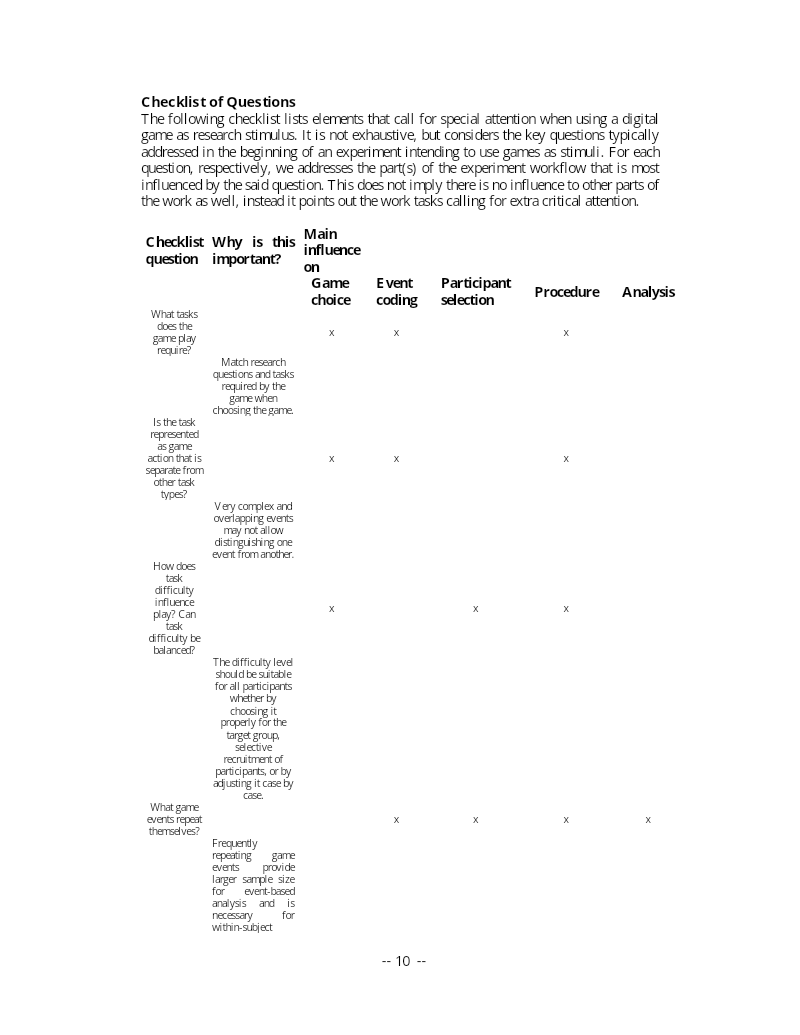
The methodology involved using the Garden of Eden Creation Kit (GECK) to extract and align dialogue across the five languages. Due to technical constraints and varying data volumes, the researchers utilized English, German, and Italian for training, while reserving Spanish and French for testing. The study employed BERT-based and RoBERTa-based models to perform sequence classification, comparing multilingual and language-specific approaches. The models were evaluated on their ability to predict sentiment labels, with the best overall accuracy reaching 54% using multilingual BERT on Spanish data.
Key findings indicate that while sentiment analysis in this domain remains challenging, multilingual models successfully transferred sentiment understanding to languages not included in the training set. The results suggest that disgust and pained sentiments are particularly difficult to predict from text alone, likely due to a reliance on non-textual audio cues. Although monolingual models showed slight performance improvements over multilingual counterparts, the overall accuracy remained consistent with typical results for complex, multilabel NLP classification tasks. The study concludes that video games represent an underutilized, high-quality data source for computational linguistics and suggests that future research should incorporate multimodal approaches, such as audio analysis, to improve sentiment detection accuracy.