Adobe Research
Organization1 report
1 document by Adobe Research in the Game Industry Library, the newest “LLMs May Not Be Human-Level Players, But They Can Be Testers: Measuring Game Difficulty with LLM Agents” (2025).
Documents
Whitepaper13 pages
LLMs May Not Be Human-Level Players, But They Can Be Testers: Measuring Game Difficulty with LLM Agents
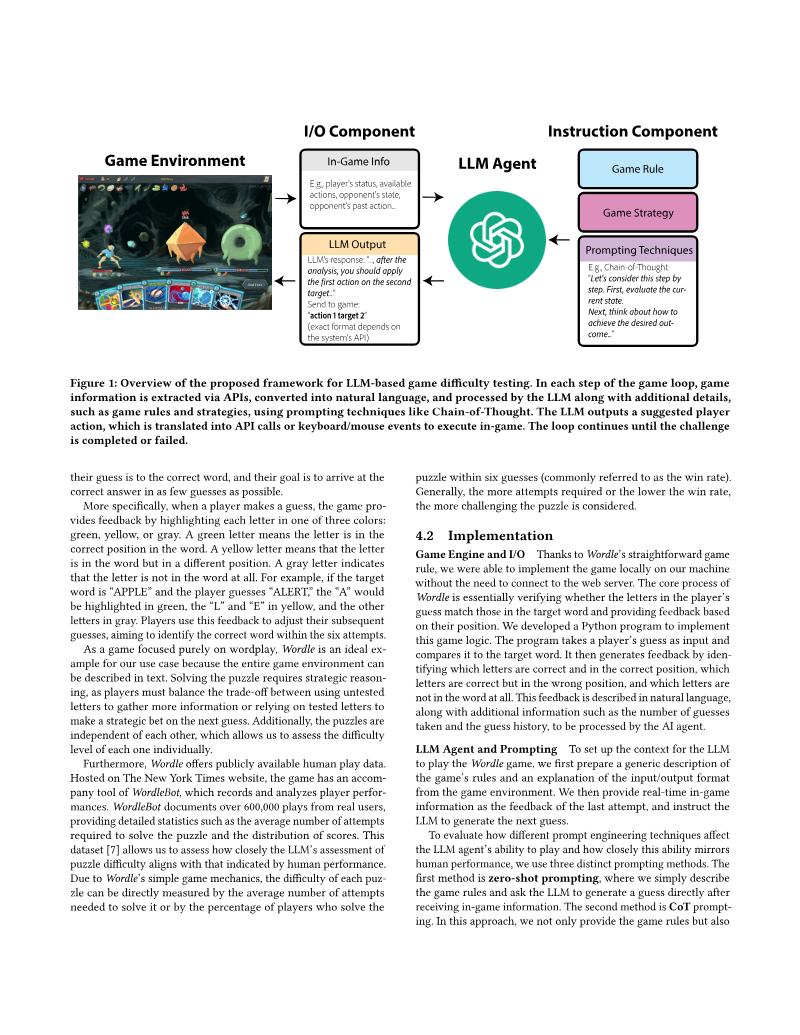
Large Language Models function as scalable, autonomous agents capable of measuring game difficulty, offering a cost-effective alternative to traditional human-based playtesting.
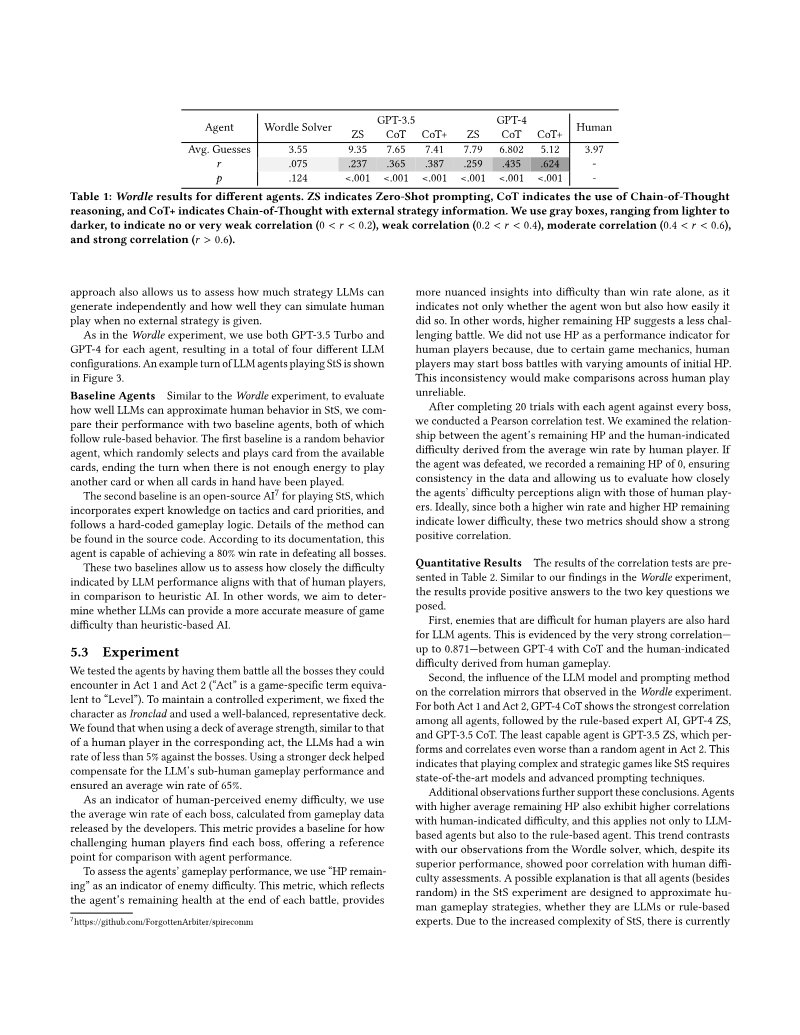
- LLMs can effectively serve as automated game testers to measure difficulty, with performance metrics showing a positive correlation to human player experience in both Wordle and Slay the Spire.
- Higher-performing LLM agents exhibit a stronger correlation with human gameplay data, as evidenced by GPT-4 with Chain-of-Thought prompting achieving a 0.624 correlation in Wordle compared to lower scores for zero-shot configurations.
- Prompt engineering techniques, specifically Chain-of-Thought (CoT) reasoning, significantly improve an LLM's ability to mirror human problem-solving, moving beyond simple random-guessing behaviors.
Adobe ResearchOct 2025
Do you work at Adobe Research? Get a free report of how these documents are read and cited here.